Automation can significantly alleviate this monotonous work by facilitating the flow of information between systems and eliminating the need for repetitive manual data entry at every stage. However, the ultimate goal is not merely to eliminate typing. Effective automation should improve the flow of information within the organization while simultaneously streamlining verification and maintenance processes. This requires more than simply linking two software programs. Organizations must understand the source of the information, determine which records should serve as the definitive source, assess which data require verification, and identify which steps still necessitate human oversight.
Find the Repeated Data Before Automating It
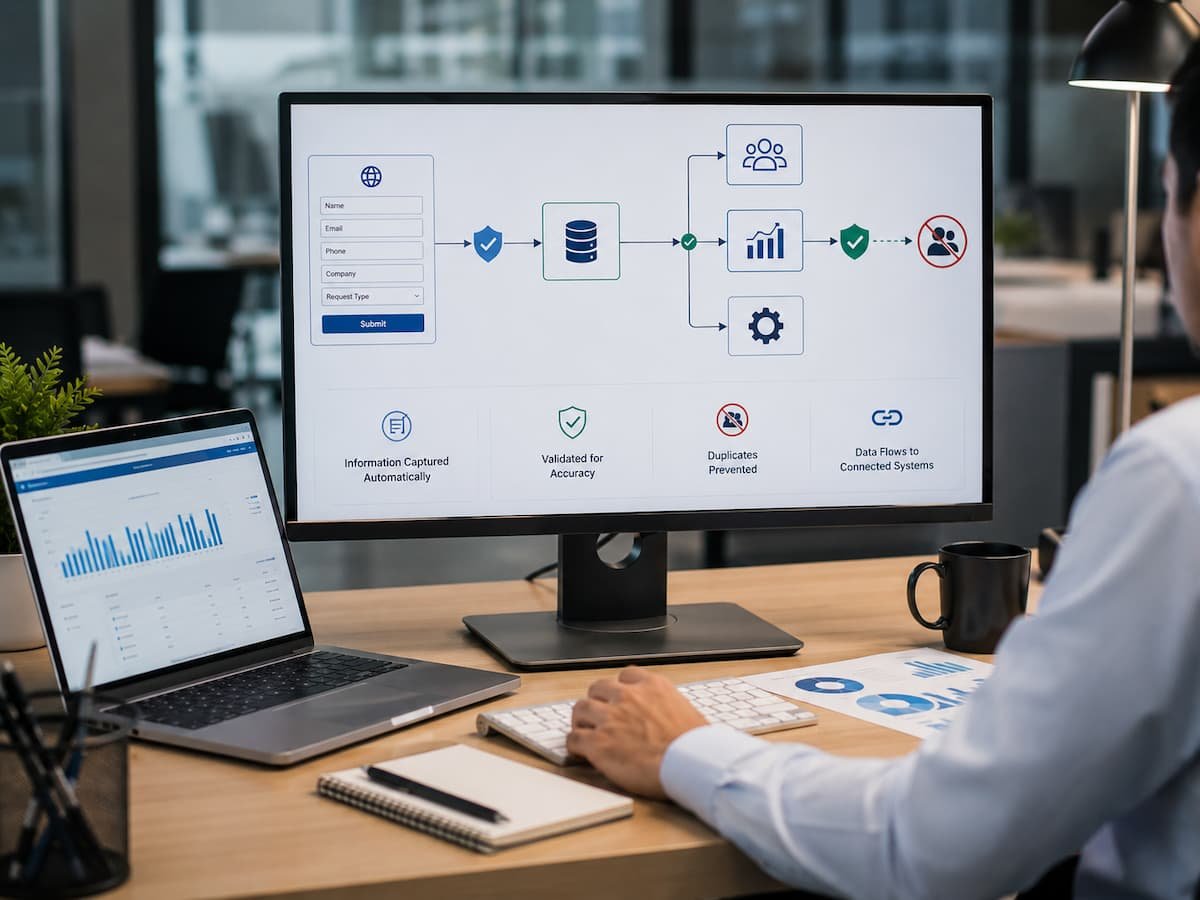
The first step is to find data that employees enter in different places over and over again. This is often far simpler than attempting to automate an entire business process. For instance, a potential customer might enter their name, email address, company name, phone number, and details regarding their inquiry into an online form. If employees then copy these fields into three separate systems, there is clearly room for improvement. Start by tracking a single, specific piece of data within the company. Choose a simple item, such as a customer’s email address or order number. Record where the data was originally created, the locations where it is repeatedly submitted, the individuals associated with it, and its final destination. You might discover that the same information is being submitted far more frequently than expected.
Look especially closely at repetitive tasks such as:
- Copying form submissions into spreadsheets.
- Entering customer details into multiple systems.
- Moving order information between applications.
- Creating records from incoming requests.
- Updating status fields across different platforms.
- Preparing recurring reports from the same source data.
- Transferring information from emails into internal systems is another example.
The best candidate is usually the task that looks least complicated. It is the task where the same information is repeatedly transferred using predictable rules.
Enter Information Once Whenever Possible
One of the simplest principles behind effective data automation is to avoid asking people to enter the same information more than once. If reliable information already exists in one system, another system should ideally receive that information electronically rather than requiring a second manual entry. Suppose a customer completes an online registration form. Once the required information has been validated, an automation can create or update the corresponding customer record. If the business later needs the same customer information for another workflow, that workflow can use the existing record instead of asking an employee to retype everything.
This reduces more than typing. It also creates fewer opportunities for inconsistent information. Imagine an employee enters a customer’s phone number correctly in one system but accidentally reverses two digits when entering it somewhere else. The company now has two versions of the same information. The problem may not become visible until someone tries to contact the customer. When the business captures information once and reuses it carefully, it has a better chance of maintaining consistent records.
Choose a Reliable Source of Truth
Automation can move information quickly, but it cannot decide which version of conflicting information should be trusted unless the business establishes that rule. This is why a reliable source of truth matters. A business might maintain customer information in a customer management system, while order information lives in an order-management system. The important point is that employees should know which system is authoritative for each type of information.
Without that distinction, automation can create a strange problem: several systems stay synchronized while all of them contain the wrong information. Before building a data-entry automation, decide where the original information should live and which systems are simply receiving or using it.
A simple data ownership approach
- Decide which system owns each important type of information.
- Avoid maintaining independent versions of the same record when possible.
- Define which system can update particular fields.
- Determine how changes should be passed to connected systems.
- Document what should happen when two sources disagree.
This may sound like a technical detail, but it has a direct effect on everyday work. Employees are less likely to waste time deciding which record is current when the business has already established where authoritative information belongs.
Use Forms to Improve the Information Coming In
Many data-entry problems begin before automation even starts. If employees receive incomplete or inconsistent information, the workflow has to deal with the mess later. A well-designed form can prevent some of these issues. Required fields can ensure that essential information is present. Standardized selections can reduce variations in categories. Clear instructions can discourage people from entering information in the wrong format.
For example, asking employees to type a department name manually can produce values such as “Sales,” “sales,” “Sales Team,” and “Sls.” A predefined selection creates a consistent value that an automation can use more reliably. This illustrates an important principle: effective automation begins with good inputs. If the information entering the workflow is predictable, the rules that follow can be simpler. If the input is inconsistent, the automation may need complicated cleanup logic that becomes difficult to maintain.
Validate Information Before Sending It Somewhere Else
Removing manual data entry does not mean sending every piece of information directly into another system. Validation should happen before important records are created or updated. A workflow might verify whether a required identifier exists, whether an email address follows an expected format, whether a date is valid, or whether a customer already has an existing record. These checks do not need to be complicated. Even basic validation can prevent a large amount of downstream cleanup.
Useful validation checks include:
- Required fields are completed.
- Numbers fall within reasonable ranges.
- Dates are valid and logically ordered.
- Email addresses follow an expected format.
- Reference numbers match existing records.
- Duplicate records are identified before creation.
- Status values match the business’s approved options.
The workflow should have a clear response when validation fails. It might return the information for correction, send it to a review queue, or notify an employee. Quietly passing bad information to the next system is usually the least desirable option.
Be Careful With Duplicate Records
Duplicate records are one of the most common ways automated data entry can create long-term administrative problems. The workflow may be doing exactly what it was told to do: create a new record whenever a new submission arrives. The problem is that the submission may belong to an existing customer or transaction. Before creating a new record, determine what makes it unique. An email address may be useful in one situation, while a customer number or order identifier may be more appropriate in another.
Names alone are often unreliable identifiers because multiple people can have the same name, and the same person may enter their name differently on different forms. When the system cannot confidently determine whether two records are the same, the workflow can pause and request human review rather than making an uncertain decision automatically. That small amount of caution can prevent a much larger cleanup project later.
Do Not Automate Every Data Correction
Automation is excellent at predictable transformations. It becomes less reliable when information requires interpretation. For example, changing a date from one known format into another is usually straightforward. Deciding what a customer meant when their description is unclear is a different problem. Businesses sometimes make the mistake of creating increasingly complicated rules to handle ambiguous information. Eventually the workflow contains dozens of special cases, and employees no longer know why certain records are being treated differently. A better approach is to automate predictable corrections and route uncertain cases to a person.
Keep human review when:
- The information is ambiguous.
- Multiple records could be a possible match.
- The decision could materially affect a customer or transaction.
- The system lacks enough information to make a reliable choice.
- The correction requires understanding context rather than applying a fixed rule.
The purpose of automation is not to eliminate every human interaction. It is to make sure people spend their time where their judgment actually adds value.
Connect Systems Carefully
Connecting two applications can make a workflow much more efficient, but every connection introduces another dependency. If one system changes a field, permission, format, or process, the automation may behave differently. Before connecting systems, understand what information needs to move between them and why. Do not transfer every available field simply because the integration allows it. Extra information creates additional dependencies and makes the workflow harder to understand.
A focused integration is usually easier to maintain. For example, if a customer registration process only requires a name, email address, customer type, and registration date, there is probably no reason to transfer unrelated internal fields. Keeping the connection limited to information that actually serves the next process can reduce unnecessary complexity. It is also useful to document what happens when the receiving system is temporarily unavailable. Information should not simply disappear because a connected application failed to respond.
Automate the Boring Parts of Reporting
Manual data entry does not always involve creating records. Employees often spend significant time collecting information for recurring reports. Someone may export a spreadsheet every Monday, copy figures into another workbook, clean the formatting, calculate totals, and email the finished report to a manager. If the same data sources and calculations are used repeatedly, much of that process may be automated. The important distinction is between collecting and interpreting information. Automation can often gather current data, combine predefined sources, perform routine calculations, and prepare a report. A manager may still need to interpret what the numbers mean and decide what action should follow. This arrangement saves preparation time without pretending that software can automatically understand every business situation.
Watch for Automation That Creates More Data Than People Need
There is another problem that receives less attention: automation can create too much information. A business might configure a workflow to record every minor event, send notifications for every update, and create tasks whenever a small status change occurs. The system is technically active, but employees may become overwhelmed by the volume. More records and notifications do not automatically mean better information.
When automating data movement, please consider whether the receiving person actually needs the information. If a field is only being transferred because it happens to be available, consider leaving it out. If a notification requires no human action, it may be unnecessary to send it. Effective automation reduces unnecessary work on both sides. It should decrease manual entry without replacing it with manual sorting through a flood of automated output.
Make Errors Easy to Find
Even a carefully designed workflow can encounter problems. A connected system can become unavailable, an unexpected value can appear, or a record can fail validation. What matters is whether the business can identify and recover from the problem. Important workflows should provide some way to see unsuccessful actions. Employees responsible for the process should know when something needs attention and what information is available for troubleshooting.
For example, if a required field is missing, the workflow should show that the customer record could not be created. “Automation failed” is much less useful than knowing exactly which condition prevented the record from being processed. Clear error handling also prevents employees from unknowingly working with incomplete information.
A useful error-handling process can include:
- Recording the failed transaction.
- Identifying the reason for failure.
- Notifying the appropriate person.
- Preserving the original information for review.
- Allowing safe correction and retry when appropriate.
Measure the Work You Actually Removed
Automation should produce a measurable improvement, even if the measurement is simple. Before changing a process, estimate how much manual work is involved. After implementation, please verify if the amount of manual work has truly decreased. You might measure how many records employees enter manually, how many corrections are required, how long a recurring process takes, or how many duplicate records appear each month. Do not focus only on the number of automated actions. A workflow can perform thousands of actions and still provide little benefit if employees must constantly correct its results. Better measurements often include:
- Time spent on manual data entry.
- Number of repeated entries removed.
- Data correction frequency.
- Duplicate record frequency.
- Processing time for routine requests.
- Number of exceptions that require manual attention.
These measures show whether automation is actually improving the process rather than simply making it more technologically sophisticated.
Start Small Before Connecting Everything
For example, a company might begin by automating the flow of new client form submissions into its core customer system. It could then automate the production of notifications and tasks. Once you have proven these parts reliable, you can hook up other systems. This phased method makes it easy to pinpoint when you introduced an issue. It also provides employees with time to learn the new method, rather than forcing them to adapt to a big set of changes all at once.
Review Automations When Business Changes
A workflow that works well now may become problematic when the business changes. You can add new fields to forms. Another system may be used by employees. Products may be renamed. Customer processes will alter. Something that was logical at one point in a regulation may not be how work is really completed anymore. Automation hence requires maintenance.
Review key workflows as connected systems change and periodically validate if the automation still fits the business process. Look at error rates, manual corrections, duplicate records, and employee feedback. Watch for employees who are constantly creating workarounds. A workaround is generally a sign that the automated procedure doesn’t reflect reality. The remedy may be to tweak the automation, change the process, or intentionally send a specific step back to a person.
Smart Automation Boosts Information Trustworthiness
Less manual data input doesn’t mean there will be fewer fields to type for employees; the true gain is It is that information can be flowing via the firm with less unneeded opportunity for errors. This means taking a deliberate approach. Find duplicate data transfer. Capture information correctly at the beginning. Check vital fields. Build credible sources of truth. No repeated entries. Let humans make the uncertain decisions. When the surrounding business changes, look for failures and examine the workflow.
Once those parts are in place, automation is no longer just a shortcut. It creates a more direct route for information to flow from the point of creation to the point of application by a person. The ideal automated data-entry procedure is the one that employs scarcely notice. Records are consistent where the information should be. Routine work is done without having to rekey. People can spend their time validating critical details, not copying them from screen to screen.”
FAQs
1. What are the simplest sorts of data entry to automate?
Repetitive data entry is sometimes the easiest way to go, where the fields are predictable and the rules are clear. Examples include moving form submissions, creating records from approved requests, updating known status data, and moving recurring information between connected systems.
2. Can automation totally replace the need for manual data entry?
Not always, no. Some information must be interpreted, verified, or corrected by humans. A better goal is to eliminate needless duplication of input but to keep people in the loop if information is uncertain or an important decision needs to be made.
3. How can automating reduce data entry mistakes?
Automation improves accuracy by allowing information to be input once and reused, by checking required fields, standardizing values, detecting duplicates, and by minimizing the number of times employees have to manually copy information between systems.
4. What to do when automation returns wrong data?
The workflow should make the problem evident and provide a clear path for correction. Depending on the circumstances, it can stop the process, transmit the record for review, ask for missing information, or let a repaired record be securely processed again.
5. Which is better: to automate one system or to connect numerous systems?
Begin with the tiniest connection that addresses a significant issue. The workflow is stable, and then they can add other systems incrementally. It’s easier to test, troubleshoot, and maintain than putting out a vast network of integrations right now.