A CRM migration is often described as a technology project, but one of its biggest risks exists long before any records are imported. Customer data that has accumulated across spreadsheets, legacy CRMs, email systems, support platforms, sales databases, and other tools rarely arrives in a clean, consistent format. Names may be entered differently, companies may appear under several variations, old contacts may still be active, and important relationships can be stored in ways the new CRM does not understand.
Moving that data without organizing it first simply transfers the existing problems into a new system. In some cases, the new CRM makes those problems harder to identify because it connects records to workflows, reports, automations, permissions, and other processes. Microsoft identifies schema differences, incomplete or duplicate data, relationship complexity, security, and validation as important considerations in CRM migrations. (Microsoft Learn)
The better approach is to treat migration as an opportunity to decide what customer information the business actually needs going forward. Instead of asking, “How do we move everything?” the more useful question is, “Which customer information deserves to become part of the new operating system?” That change in thinking can reduce unnecessary data, improve trust in the new CRM, and make the migration much easier to manage.
The First Decision: What Should Actually Move?
The temptation to migrate everything is understandable. Old records can feel valuable simply because they exist, and deleting information before a migration can make stakeholders nervous. But historical volume is not the same as business value. A customer record that has not been touched for years, contains incomplete information, and has no foreseeable operational purpose may not deserve the same treatment as an active customer relationship.
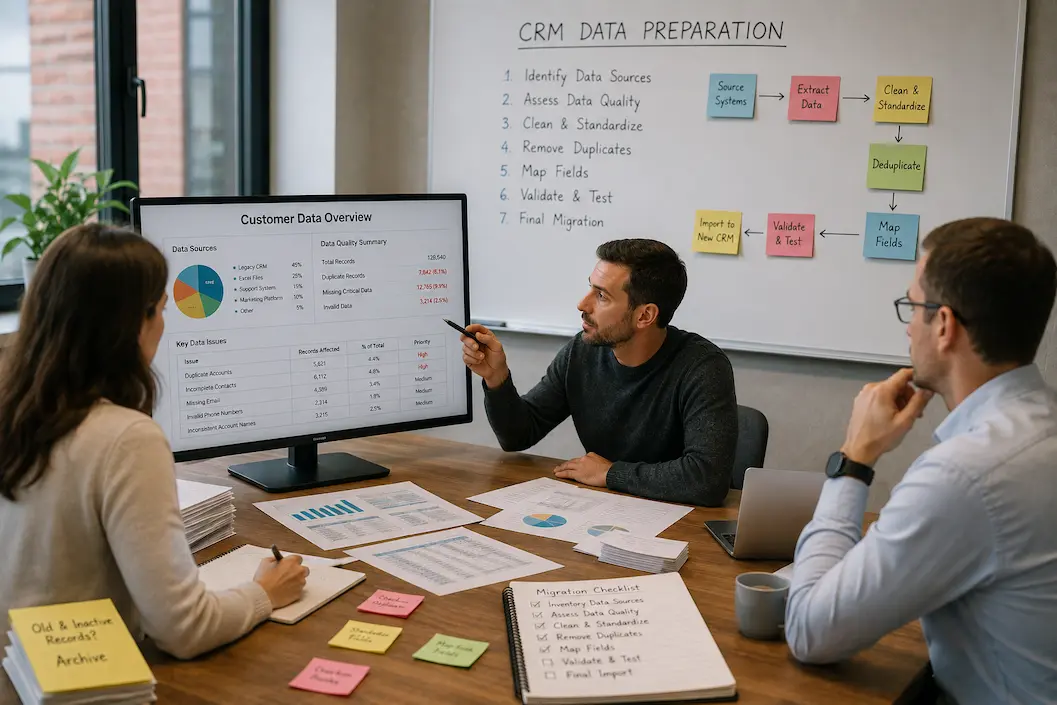
Start by creating an inventory of the data sources involved. Include the current CRM, spreadsheets maintained by sales teams, customer service systems, marketing platforms, ecommerce databases, accounting-related customer records, and any departmental files that contain information employees rely on. The goal at this stage is not to clean anything. It is to understand how much data exists, where it lives, who owns it, and what role it currently plays.
For each source, document the major record types and approximate volumes. You might discover that the sales CRM contains accounts and opportunities, while a support platform contains contacts and service history, and several spreadsheets contain additional customer classifications. This inventory gives the migration team a much more realistic picture than simply exporting the old CRM and assuming that represents the entire customer dataset.
A useful way to classify records is by business purpose, rather than by the system they came from. Ask whether each dataset supports active selling, customer service, reporting, compliance, relationship history, segmentation, billing coordination, or another legitimate operational need. Information that has no identifiable purpose should be questioned before it becomes part of the new CRM.
Build a Data Inventory Before Cleaning Anything
The data inventory should become the working map for the migration. For every important dataset, record its source, owner, record type, approximate size, update frequency, sensitivity, and intended destination in the new CRM. This prevents teams from discovering important sources halfway through the project.
It is also useful to identify the person responsible for deciding whether each dataset is accurate and necessary. A CRM administrator may understand the technical structure, but a sales manager may know whether a particular customer status field still has business meaning. Likewise, customer service leadership may be better positioned to decide whether years of support history are operationally important.
A simple inventory might contain columns such as:
- Data source
- Record type
- Business owner
- Approximate record count
- Key identifiers
- Known quality problems
- Intended CRM destination
- Migration decision
- Retention or archive decision
The important point is that the inventory should lead to decisions. A spreadsheet that merely lists hundreds of fields without identifying who owns them or why they matter becomes another piece of documentation nobody uses.
Separate Customer Records From Customer History
One of the most useful distinctions during a migration is the difference between current customer information and historical activity. They should not automatically be treated as one dataset.
A contact’s current email address, phone number, job title, and relationship status may be essential to daily operations. An interaction from eight years ago may be useful for historical context but unnecessary for everyday workflows. Similarly, an old opportunity may need to be retained for reporting or audit purposes without requiring every associated note to appear in the primary working view.
This distinction can reduce migration scope considerably. Microsoft recommends identifying and excluding nonessential data early, particularly where migration complexity or data volume creates additional risk. (Microsoft Learn)
For each historical dataset, ask three questions: Who needs it? What decision does it support? What happens if it is not available in the new CRM? If the answer is vague, the organization should consider archiving rather than migrating it into the active customer environment.
Archiving also needs a deliberate policy. “Archive everything else” is not enough. Decide where archived information will live, who can access it, how long it should be retained, and whether employees need a practical way to retrieve it. Retention requirements should be handled with the appropriate legal, privacy, and compliance stakeholders rather than guessed by the migration team.
Find Duplicates Before They Become a New CRM Problem
Duplicate records are one of the most damaging forms of migration debt because they can multiply the number of customer records while making the business believe it has a complete customer view. One company might appear as “Northstar Manufacturing,” “North Star Mfg.” and “Northstar Manufacturing Inc.” while the same individual could appear under different email addresses or variations of their name.
The answer is not to merge everything that looks similar. Deduplication requires matching rules that distinguish genuine duplicates from legitimate separate records. Microsoft recommends using normalization and progressively testing matching rules, while Salesforce provides duplicate and matching mechanisms intended to help organizations maintain trusted records. (Microsoft Learn)
Begin with strong identifiers where available. An exact email address can be a useful contact-level signal, while a company domain, external customer ID, account number, or another stable identifier may help establish relationships between records. Names and addresses can support matching, but they should generally be treated more carefully because common names and shared addresses can produce false matches.
The hardest question comes after identifying duplicates: which information should survive? Suppose two records represent the same customer but one contains a newer phone number while the other has a more complete address. A simple “keep the newest record” rule may discard useful information. Define survivorship rules before mass merging so that important fields are handled consistently. Microsoft documentation describes approaches such as choosing the most complete or most recent record and, where appropriate, combining field values from matched records. (Microsoft Learn)
Standardize the Data Without Destroying Meaning
Cleaning is not simply about making every value look identical. The purpose of standardization is to make information consistent enough that the new CRM can use it reliably.
Consider a customer status field containing values such as “Active,” “active customer,” “Current,” “Yes,” and “1.” These values may have been perfectly understandable within separate systems, but they become problematic when combined. The migration team needs to determine what the values actually mean and map them to a controlled set of CRM values.
The same issue appears with countries, states, job titles, industries, phone numbers, lead sources, customer tiers, and many other fields. Free-text fields deserve particular scrutiny because employees may have used them as informal substitutes for structured fields.
Normalization should therefore be based on a data dictionary. Define the accepted value, meaning, format, and usage of important fields before transformation begins. Microsoft recommends normalization to handle variations in customer data, including differences in how addresses and other values are entered. (Microsoft Learn)
Do not standardize values simply because they look different. First determine whether the difference carries business meaning. Changing two distinct customer categories into one value may improve consistency while simultaneously destroying information the business relies on.
Create a Field Map That Explains More Than Names
Field mapping is where many migrations become unexpectedly complicated. A source field called “Customer Type” may not correspond directly to a target field with the same name. The source may use three categories while the new CRM expects five. Another field may need to be split into multiple values, combined with another field, converted to a different format, or eliminated entirely.
A useful field map should therefore document more than source field → target field. It should explain the transformation required and who approved it.
| Mapping question | What to document |
|---|---|
| Where does the value come from? | Source system and field |
| Where does it go? | Target object and field |
| Is transformation required? | Conversion or normalization rule |
| Is the target field mandatory? | Yes/no and handling method |
| What happens to blank values? | Leave blank, derive, review, or exclude |
| Who owns the decision? | Business or technical owner |
| How will it be tested? | Validation method |
Salesforce recommends creating an offline data dictionary or source inventory and reviewing field-level data before mapping. (Salesforce) This is particularly important when several source systems are being consolidated into one CRM.
The field map should also identify fields that deliberately will not be migrated. That decision is valuable documentation because it prevents someone from reopening the same question weeks later.
Preserve Relationships, Not Just Rows
Customer data becomes much more valuable when its relationships remain intact. A contact without the correct account association, an opportunity without its customer, or a support record without its related contact can technically appear in the new CRM while losing much of its usefulness.
Before migration, identify the relationships between major record types. Determine which records are parents and which depend on them. Salesforce specifically recommends mapping relationships between selected objects and planning migration order around those dependencies. (Salesforce)
This can affect migration sequencing. For example, an organization may need to establish account records before importing contacts associated with those accounts. Opportunities may then depend on the correct account and contact relationships. Service records may depend on both customer and contact identifiers.
Stable identifiers become particularly important here. If the migration changes record identifiers without maintaining a reliable cross-reference, reconnecting related records becomes significantly more difficult. Create an explicit relationship strategy before loading the data rather than attempting to repair associations after the migration.
Decide What “Good Data” Means Before You Clean It
Data quality is often discussed too vaguely. A migration team may say that the data needs to be “clean,” but that does not provide a measurable standard.
Instead, define quality criteria for the fields that matter most. For example, an active customer might need a valid account name, an identified owner, a usable contact method, a defined customer status, and a unique identifier. Historical records may have different requirements.
This distinction prevents teams from spending enormous amounts of time perfecting information that has little operational value. A field used for customer-facing communication deserves more attention than an obscure legacy field that will be archived.
Create a baseline before cleansing begins. Measure things such as missing critical values, duplicate records, invalid formats, inconsistent categories, and unresolved relationships. Then establish the level of quality required before migration.
That baseline also gives management something concrete to review. Instead of saying, “We cleaned the database,” the migration team can demonstrate that duplicate records were reduced, critical fields improved, and unresolved relationships were brought below an agreed threshold.
Do Not Let the Migration Team Make Every Data Decision
Technical teams are often placed in an uncomfortable position during data cleanup. They have the tools to identify problems but may not understand the business meaning behind every field.
A sales operations manager may know that a particular account classification determines territory ownership. A customer service leader may understand that an apparently outdated status is still required for escalation workflows. Finance or compliance personnel may know that certain historical information must be retained even though frontline employees no longer use it.
The best migration governance therefore separates technical decisions from business decisions. Technical teams can identify duplicates, formatting errors, invalid values, and relationship failures. Business owners should decide whether information is still meaningful, whether records should be retained, and how ambiguous values should be interpreted.
This prevents a technically clean dataset from becoming a business-inaccurate one.
Test the Organized Data Before You Trust It
Cleaning and mapping are not finished when the spreadsheet looks correct. The data needs to be tested in the destination environment.
A test migration should use a representative sample rather than only a handful of perfect records. Include active customers, duplicates, incomplete records, unusual customer structures, historical records, multiple contacts per account, and records with relationships to other objects.
Then verify more than record counts. Check whether fields landed in the correct locations, relationships survived, dates and numbers were transformed correctly, duplicate rules behaved as expected, and important customer information remained accessible.
HubSpot’s migration checklist similarly recommends cleaning the source data, defining object and field mappings, preparing associations, running a test import, and reviewing the imported objects before proceeding. (HubSpot) Microsoft also emphasizes validation because schema mismatches, data quality problems, relationships, and system dependencies can affect migration integrity. (Microsoft Learn)
A successful test is not simply “the records imported.” The stronger question is whether employees can use the migrated records to perform real business tasks.
The Migration Cutoff Needs Its Own Plan
Customer data can continue changing while the migration team is preparing the new environment. New customers may be created, phone numbers may change, opportunities may progress, and service records may be added.
That means the dataset used for testing will eventually become outdated. Organizations need a clear cutoff and a plan for handling changes made between the initial extraction and final migration. Depending on the systems involved, this may involve a final export, a delta migration, a controlled freeze, or another synchronization method.
The exact approach depends on the technology and business requirements, but the principle is universal: do not assume the source database stays still while you prepare the destination.
A migration plan should identify when data entry stops in the source system, who communicates the cutoff, how late changes are captured, who performs the final validation, and what happens if the final dataset fails an acceptance check.
A Cleaner Migration Starts With Fewer Unnecessary Decisions
The most effective CRM migrations are not necessarily the ones that move the largest amount of information. They are the ones that create a dependable customer foundation without carrying years of unnecessary inconsistency into the new platform.
That requires making deliberate choices before migration: which records matter, which sources are authoritative, which duplicates represent the same customer, which fields have real business value, how values should be standardized, which relationships must survive, and what level of data quality is acceptable.
The process can be summarized as:
Inventory → Classify → Clean → Standardize → Map → Relate → Test → Approve → Migrate
Each stage reduces a different type of uncertainty. Skipping one may save time initially but can shift the work into a much more expensive stage later, when incorrect data is already connected to CRM workflows and users are depending on it.
Frequently Asked Questions
Do we need to migrate all historical customer data?
No. Historical information should be evaluated based on its operational, reporting, legal, or business relevance. Some data is best kept in an active CRM system, while other data is better suited for archiving. The decision should be based on a clear objective, not on the assumption that old data is inherently valuable.
When should duplicate records be merged?
Ideally, duplicates should be identified and corrected before the final migration. Organizations should first establish matching and persistence rules to prevent legitimate, independent records from being merged incorrectly. Generally, a weak match should carry less weight than a strong match.
Who should authorize the CRM data mapping?
The business owner and the CRM technical professionals should jointly share this responsibility. The technical team understands the system architecture and the requirements for transformation. The business owner understands the meaning and purpose of the fields. A clearly designated executive within the company should make key decisions regarding mapping.
Preparing Data for a Reliable CRM System
No new system can compensate for customer data that a company has never properly organized. If employees discover duplicate accounts, conflicting contact details, unclear categories, or broken relationships immediately after the system goes live, their confidence in it can quickly erode. Teams often revert to spreadsheets and makeshift solutions, leading to a recurrence of information fragmentation.
The preparation stage is therefore much more than technical housekeeping. It is the point where an organization decides what its customer information should mean, which data deserves to be preserved, and how different teams will share a common view of customers.
When the migration starts with a clear inventory, careful cleansing, documented mapping, preserved relationships, measurable quality standards, and realistic testing, the new CRM has a foundation that employees can trust. That foundation makes later CRM implementation, automation, reporting, customer intelligence, and workflow improvements substantially easier to build and maintain. (Microsoft Learn)